Closing the loop: turn every AI failure into a test
Traces, evals and guardrails only watch on their own. Connect them and your AI gets better every week. Even OpenAI learned this the hard way with a GPT-4o update it rolled back within days.
Traces, evals and guardrails only watch on their own. Connect them and your AI gets better every week. Even OpenAI learned this the hard way with a GPT-4o update it rolled back within days.
A dealership chatbot agreed to sell a new SUV for $1. Prompt injection is OWASP's #1 risk for LLM apps. Here's what a guardrail is, what it checks on the way in and out, and the open-source tools to add one.
Same model name, same prompt, completely different behaviour. Stanford researchers watched GPT-4 go from 97.6% to 2.4% on one task. Here's the cheap weekly habit that catches drift before your users do.
Most 'evals' are a glance at the output and a shrug. Air Canada and Cursor show what that costs. Your first real eval needs no framework: read real outputs, write down what good means.
Everyone is building with AI. Very few teams can prove it works. Here's the one loop this series teaches: trace it, test it, guard it, improve it.
TypeSafe's Jev claims to be 193.6× faster and 444.6× cheaper than big chat models. Independent testers measured about 3.6×. Here's what's real, what's marketing, and what most coverage missed.
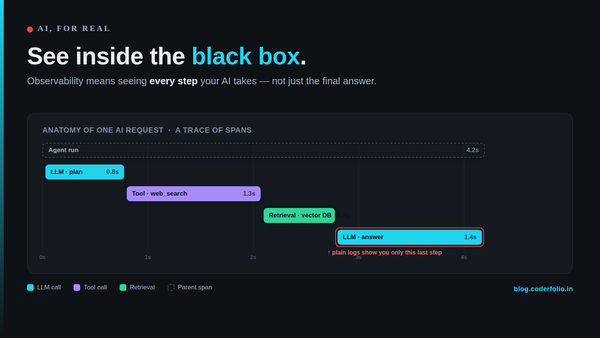
The words that matter (observability, tracing, evals), the top tools open-source and paid, and how to pick — with sources.
This is AI, for real, a brand new site by CheLvas that's just getting started. Things will be up and running here shortly, but you can subscribe in the meantime if you'd like to stay up to date and receive emails when new content is published!